Business-state rewards
Booking and CRM checks score what the agent did.
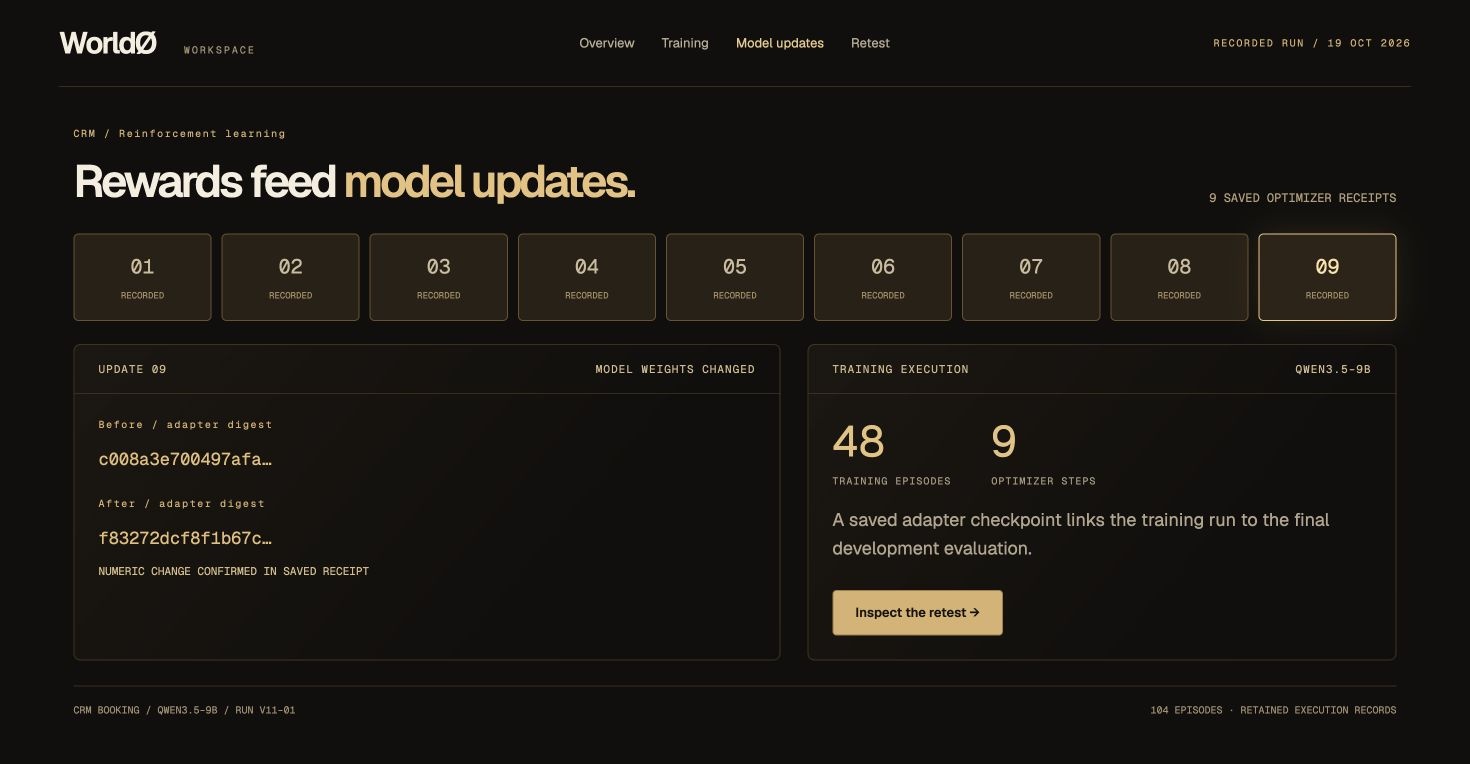
Qwen3.5–9B completed 48 training episodes and nine model updates in the CRM booking environment, followed by 16 development episodes.
Same CRM development episodes.
Seven improved · one regressed · eight unchanged.
Booking and CRM checks score what the agent did.
Nine optimizer receipts record changes to model weights.
The updated adapter is retained alongside the final evaluation.
40 baseline episodes · 48 training episodes · 16 final development episodes.
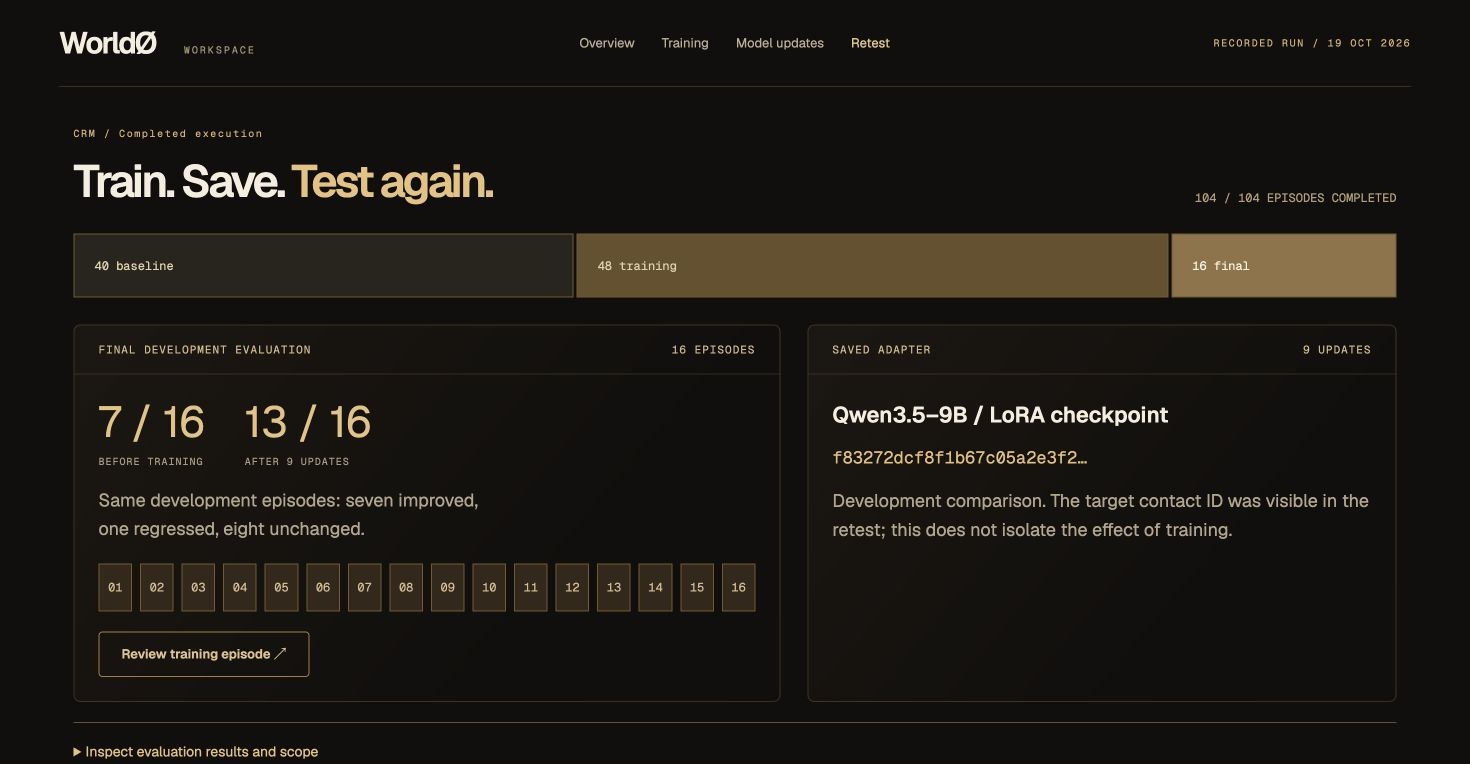
The recorded development results were 7/16 before training and 13/16 afterward: seven improved, one regressed and eight were unchanged. These are repeated development cases, not held-out tasks. The final observations exposed the target contact ID, so the result does not establish generalised improvement or isolate the effect of training.
Of the 40 baseline episodes, 24 were training-baseline and 16 development-baseline. Three baseline output-cap stops and one training parse failure remain counted as zero. The record retains 46 tool errors. No failed attempts have been dropped.
Define what your agent needs to do, the tools it uses, and what a correct outcome looks like.